BALROG: Benchmarking Agentic LLM and VLM Reasoning On Games
A benchmark evaluating language and vision-language models as agents across game environments, reporting substantial difficulty on challenging tasks.
Conference paper · 2024Sources & confidence: Qualified confidence
Checked 2 October 2026 · AI-assisted review
arXiv bibliography, authors, version dates, DOI, conference note and abstract findings.
- BALROG: arXiv 2411.13543
Authors, 2024 submission, 2025 revision/ICLR note, DOI and reported game-agent performance limits.
What this check doesn’t establish
- Abstract and bibliographic record checked; experiments not reproduced. The specific optimal-strategy formulation requires a passage in the paper, beyond the abstract.
Confidence applies to the scope above, not every claim made by the underlying source. How confidence works
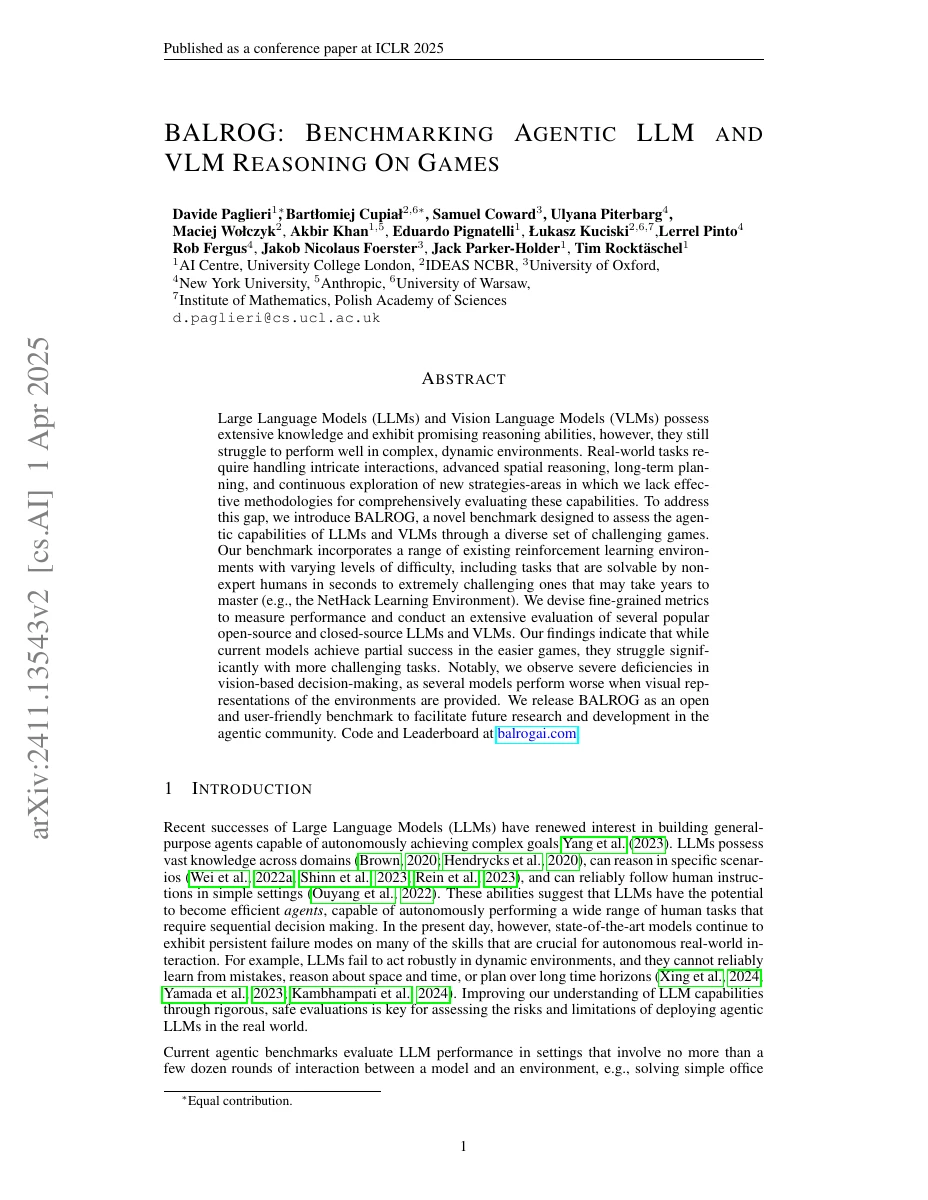
First page · arXiv:2411.13543v2
Davide Paglieri and co-authors · CC BY 4.0
BALROG evaluates models as agents in several game environments. Its abstract reports partial success on easier games and much weaker performance on harder tasks, including problems with visual decision-making.
The CivBench essay draws a comparison between those results and its own observations. That is an interpretation across different evaluations, not a replication or proof of a universal property of agents. The stronger claim that models can state optimal strategies but cannot execute them needs a specific passage beyond the abstract checked here.
The full author list is carried in the citation.
In the essays
- I Gave an AI a Civilization to Run. It Built a Nuke.
Read the essay
Ideas
- The knowing-doing gap
Subject
Record history
Catalogue source: knowledge/works/balrog.md
Generated by claude-code/claude-opus-5 on 2026-07-25